| Method | Best suited to | Typical text | Named framework | Key tools |
|---|---|---|---|---|
| Corpus linguistics | Large-scale patterns of word frequency, collocation and keyness across many texts, or one very large text | Multi-author corpora, large single-author collections, historical text archives | McEnery and Hardie’s corpus-linguistic methodology | AntConc, Sketch Engine, reference corpora such as the British National Corpus |
| Close reading / stylistics | Fine-grained analysis of how specific linguistic choices produce literary effect in a short passage | A poem, a short story, a single extract or chapter | Leech and Short’s Style in Fiction and the concept of foregrounding | Manual annotation; no dedicated software required |
| Discourse analysis | How language constructs meaning, ideology or power across a text or set of texts | Political speech, media coverage, paratexts, institutional or literary discourse with a social dimension | Fairclough’s three-dimensional model | Manual analysis, sometimes supported by corpus tools for scale |
When Corpus Linguistics Fits Your Data
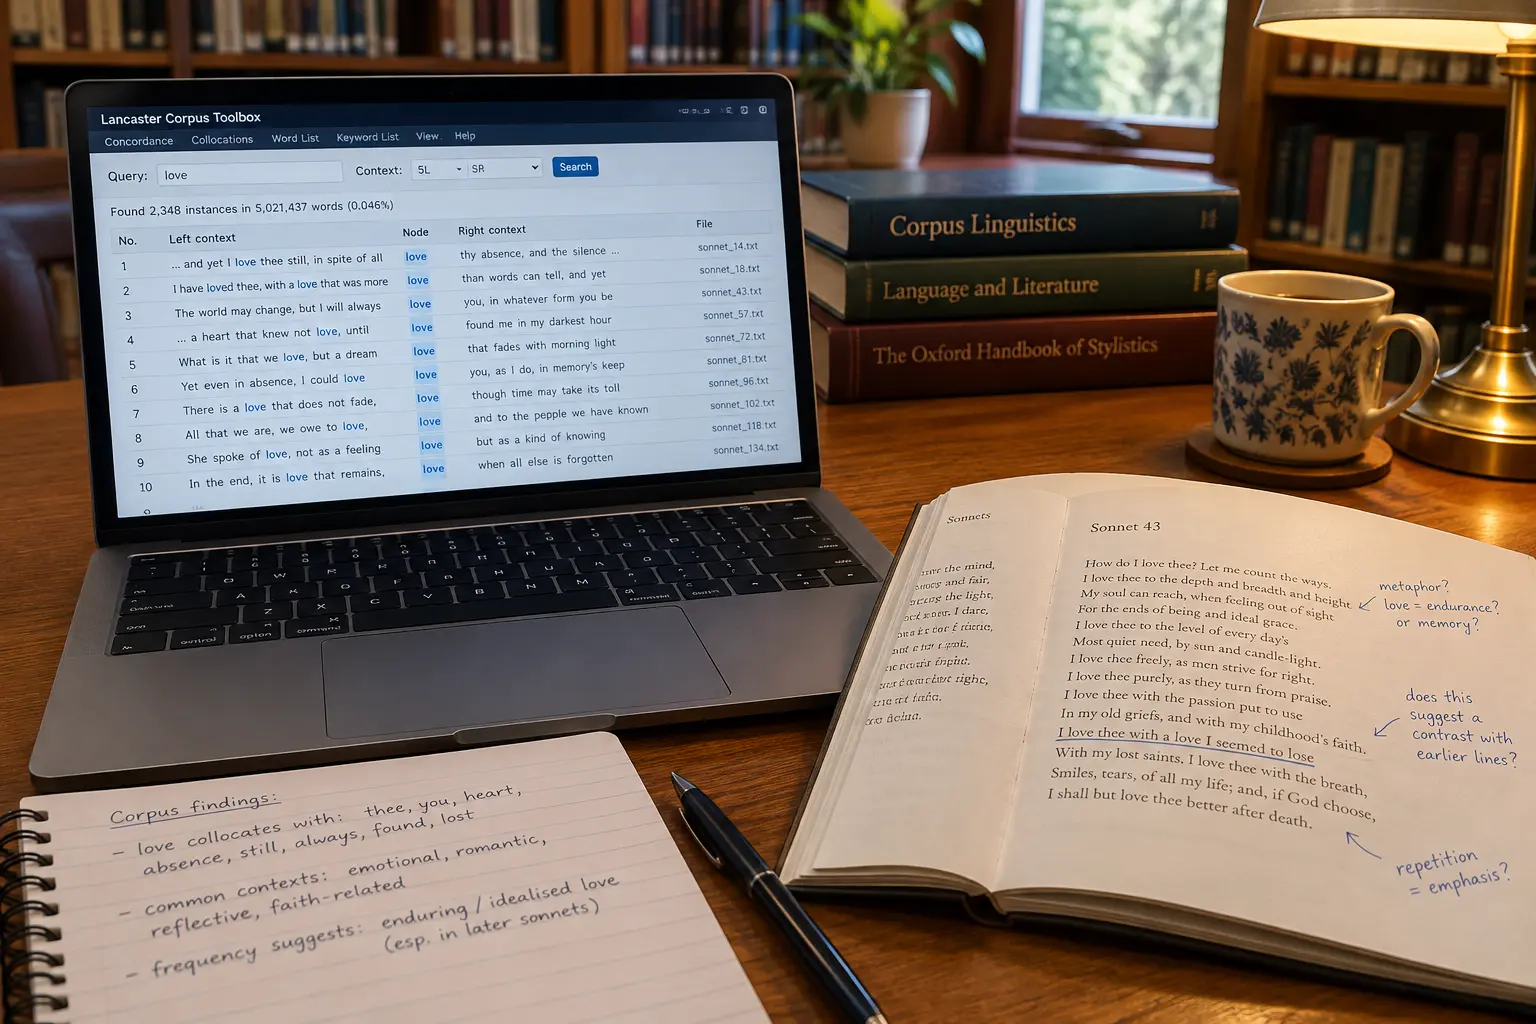
Corpus linguistics is the right choice when your research question is about patterns across a large volume of text that no human reader could reliably track by eye — how a specific word’s meaning shifts across a century of usage, how one novelist’s vocabulary differs measurably from a comparable corpus of contemporaries, how a set of political speeches use collocation to build a particular association. Tony McEnery and Andrew Hardie’s corpus-linguistic methodology structures the work around three core techniques: keyword analysis (which words appear unusually often in your corpus compared with a reference corpus), collocation analysis (which words habitually co-occur with a target word), and concordance analysis (examining every instance of a word or phrase in its immediate context, line by line).
AntConc, Laurence Anthony’s widely used desktop tool, is built around exactly this workflow, with a dedicated Keyword List function that compares your corpus against a reference corpus to surface words appearing unusually frequently. Sketch Engine goes further, generating automatic “word sketches” — corpus-derived summaries of a word’s grammatical and collocational behaviour across every grammatical relation it participates in. For a reference corpus of general English, the British National Corpus remains a standard choice: a 100-million-word corpus of written and spoken English (90% written, 10% spoken), compiled between 1991 and 1994, still widely used as a baseline against which a specialised or historical corpus can be measured for keyness. Building your own specialised corpus from scratch — digitising a historical archive, or scraping a defined set of contemporary texts — also has to be justified and documented in the methodology chapter: how the texts were selected, cleaned and balanced matters as much to an examiner as the analysis performed on them afterward.
When Close Reading and Stylistics Fit Your Data
Close reading is the right choice when your research question is about how a small number of specific linguistic choices in a short passage produce a literary effect — why a particular line of poetry unsettles a reader, how a shift in sentence structure signals a change in narrative perspective, what a single unusual word choice is doing at a pivotal moment in a novel. Geoffrey Leech and Mick Short’s Style in Fiction gives this kind of reading a systematic linguistic footing rather than leaving it purely impressionistic: their checklist of style features spans lexical, grammatical, and figurative categories, built on an eclectic linguistic foundation (drawing on transformational grammar, systemic grammar and conversational analysis among others) and organised around the concept of foregrounding — the psychological prominence a linguistic choice gains against the backdrop of ordinary usage.
Unlike corpus linguistics, close reading and stylistics do not require dedicated software; the analytical work is the close, line-by-line annotation itself, and the rigour comes from showing your reading is grounded in specific, quotable linguistic features rather than general impression. This makes the method well suited to a thesis built around a small number of primary texts examined in depth, rather than a large corpus examined for pattern.
When Discourse Analysis Fits Your Data
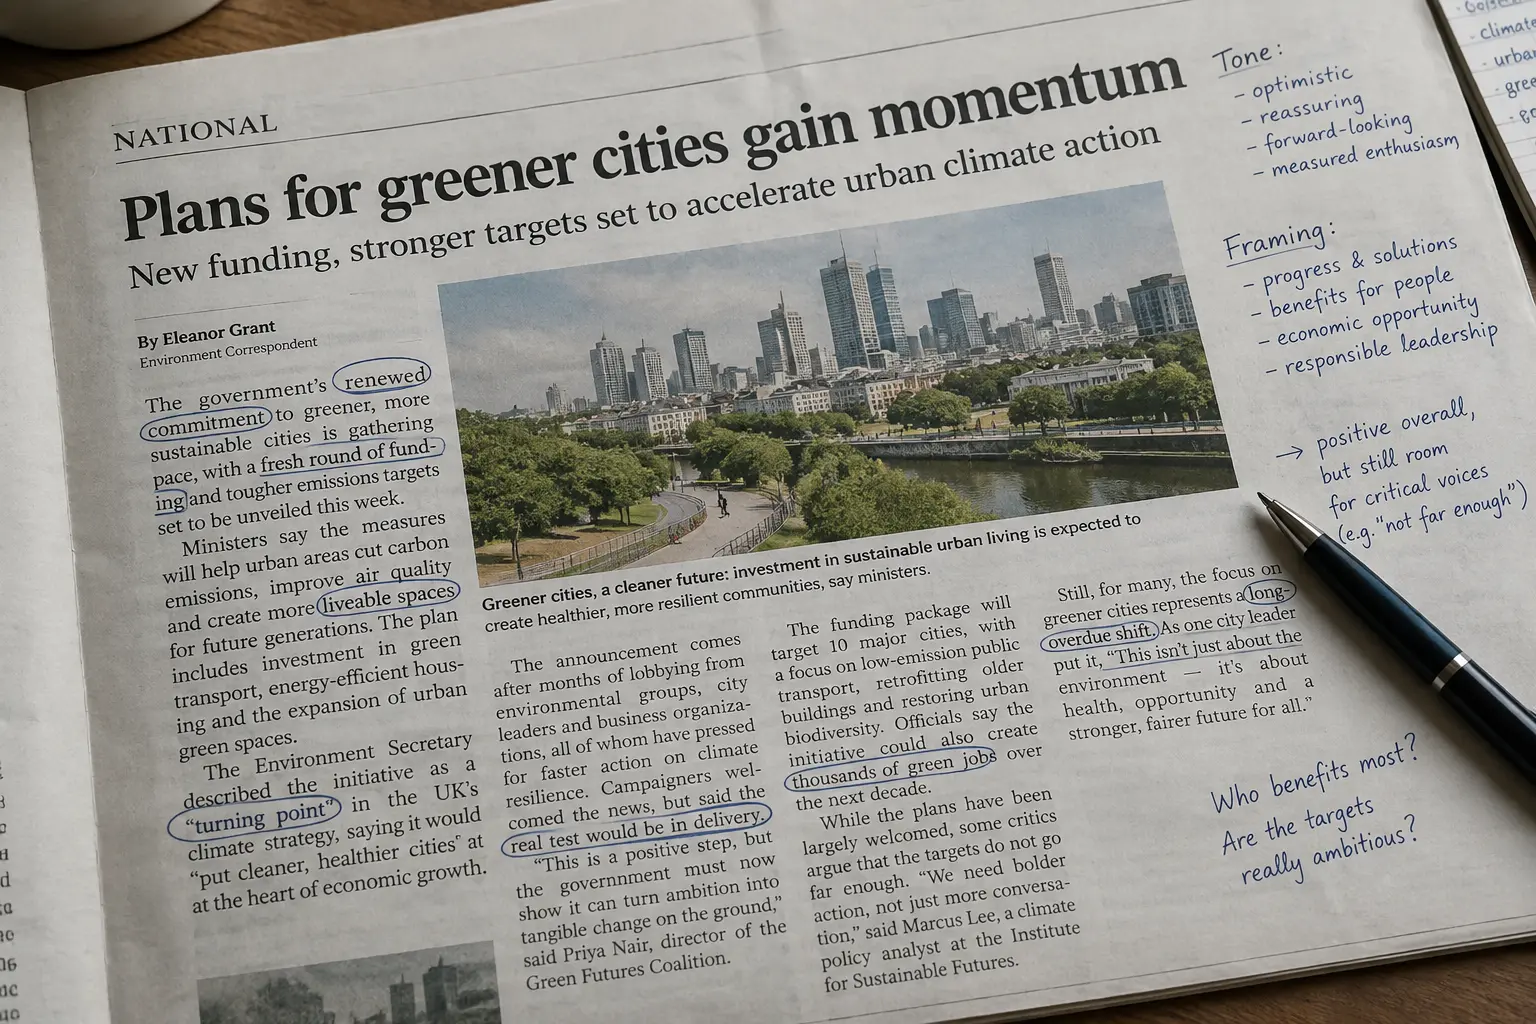
Discourse analysis is the right choice when your research question is about how language constructs ideology, power or social relations across a text or set of texts, rather than either counting patterns across a large corpus or reading closely for literary effect in one passage. Norman Fairclough’s three-dimensional model, widely used across linguistics as well as in sociology and media studies, analyses a text at three levels: description of the language itself, interpretation of the discursive practice (how the text is produced, distributed and consumed), and explanation of the social practice the text is embedded in — connecting the micro level of language choices to the macro level of ideology and social structure.
In a linguistics or literature thesis, discourse analysis typically applies best to texts with an explicit social or political dimension: how a set of book reviews construct a national literary canon, how a genre’s marketing paratexts position a readership, how a political speech or media text builds legitimacy through specific linguistic strategies. It is less suited to a single literary passage examined purely for its aesthetic effect, which is closer to what close reading and stylistics are built for.
The Same Line, Read Three Ways
An illustrative (invented) line makes the difference concrete: “The house remembered everything, though no one who lived there ever did.”
- Corpus linguistics would ask whether “remembered” collocating with an inanimate subject like “house” is unusually frequent in this author’s corpus compared with a reference corpus, and whether that collocation pattern recurs across the novel or is a one-off.
- Close reading / stylistics would treat the personification of the house as a foregrounded deviation from ordinary usage, examine the syntactic structure that sets the house’s memory against the inhabitants’ forgetting, and connect that single line to the novel’s broader thematic concerns.
- Discourse analysis would ask what ideological work the personified house does within the novel’s wider construction of memory, domesticity or inheritance, and how that construction relates to the social or historical context the text is read against.
Three legitimate, methodologically distinct readings of the same sentence — the method has to follow the research question, not the other way round.
How Does the Method Choice Affect Your Theoretical Framework?
The method and the theoretical framework are not the same decision, but they constrain each other. A corpus-linguistic project usually sits within a broadly empirical, pattern-based epistemology — the framework has to justify why frequency and collocation are meaningful evidence for the literary or linguistic claim you want to make, not just report the numbers. A close-reading project sits more naturally within a literary-critical or stylistic tradition, where the framework justifies why this particular passage, and this particular set of linguistic features, matters for the interpretive claim being built. A discourse-analytic project needs a framework that explains the relationship between language and power or ideology before the analysis starts — Fairclough’s own critical linguistics tradition, or a related approach, rather than assuming the connection is self-evident. The general worked examples for building a conceptual or theoretical framework by discipline are covered in what is a conceptual framework for a postgraduate thesis, and the same logic of connecting framework to method applies whichever of the three approaches in this comparison you choose.
Which One Should You Actually Use?
If your research question is about pattern across a large volume of text — frequency, collocation, change over time or between authors — choose corpus linguistics and be specific about your reference corpus. If your research question is about how specific linguistic choices in a small number of texts produce literary effect, choose close reading grounded in a systematic stylistic framework like Leech and Short’s, rather than leaving the analysis purely impressionistic. If your research question is about ideology, power or social construction across a text or set of texts with an explicit social dimension, choose discourse analysis and be prepared to connect the micro level of language to the macro level of social context. Many linguistics and literature theses combine corpus methods for scale with close reading or discourse analysis for depth on a smaller set of especially revealing passages — state explicitly which method is doing which job in your methodology chapter if you do this.
Whatever method you choose, the same care about limitations applies as anywhere else in this network: writing the limitations section of a linguistics or literature PhD covers corpus size, interpretive scope and single-coder reflexivity specifically, and is worth reading alongside your methodology chapter rather than left until the conclusion. Locating where your chosen method leaves a genuine gap in the existing scholarship, rather than restating a debate that is already well covered, is the same skill described for any discipline in research gap and problem statement: worked examples, and the literature review chapter that surveys prior corpus, stylistic or discourse-analytic work on your text or period is the same general task covered in you have read 300 papers and have no literature review chapter. However you draft the analysis chapters, including with Tesify, the reading and the argument stay yours — 100% written by you.
Frequently Asked Questions
What are the three core techniques in corpus linguistics?
Keyword analysis (words appearing unusually often compared with a reference corpus), collocation analysis (words that habitually co-occur), and concordance analysis (examining every instance of a word or phrase in context).
What is foregrounding in stylistics?
The psychological prominence a linguistic choice gains against the background of ordinary usage — a deliberate deviation that draws a reader’s attention and carries literary effect, central to Leech and Short’s approach in Style in Fiction.
How big is the British National Corpus?
100 million words of written and spoken English (90% written, 10% spoken), compiled between 1991 and 1994, still widely used as a general-English reference corpus.
Do I need software for close reading?
No. Close reading and stylistics are manual, line-by-line analytical work; the rigour comes from grounding the reading in specific, quotable linguistic features, not from a software tool.
Can corpus linguistics and close reading be combined in one thesis?
Yes, commonly corpus methods establish a pattern across a large text set, and close reading then examines a smaller number of especially revealing instances in depth. State explicitly which method is doing which job.
What is Fairclough’s three-dimensional model used for in literature?
Analysing how a text with a social or political dimension — paratexts, reviews, a politically engaged literary work — constructs ideology or power, by connecting the language itself to how it is produced and consumed and to the wider social context.
Which reference corpus should I use besides the BNC?
It depends on your text’s period, genre and variety of English — a historical corpus needs a period-matched reference corpus, and a specialised genre may need a genre-matched one rather than a general reference corpus like the BNC.
Is AntConc free?
AntConc is a freely available desktop application; Sketch Engine is a commercial platform with more advanced automatic word-sketch functionality, so check your university’s own licence before assuming access.
Which method is best for a single-author thesis on one novel?
Close reading and stylistics usually fit best for a single novel examined in depth, though a corpus-assisted approach comparing that novel against the author’s other works or a genre corpus can add a useful pattern-level dimension.
Does my method choice need to match my theoretical framework exactly?
They need to be compatible rather than identical — a corpus-linguistic method needs a framework that justifies treating frequency and pattern as meaningful evidence, a close-reading method needs a literary-critical or stylistic framework that justifies the interpretive weight placed on specific features, and a discourse-analytic method needs a framework that already explains the relationship between language and power before the analysis begins.