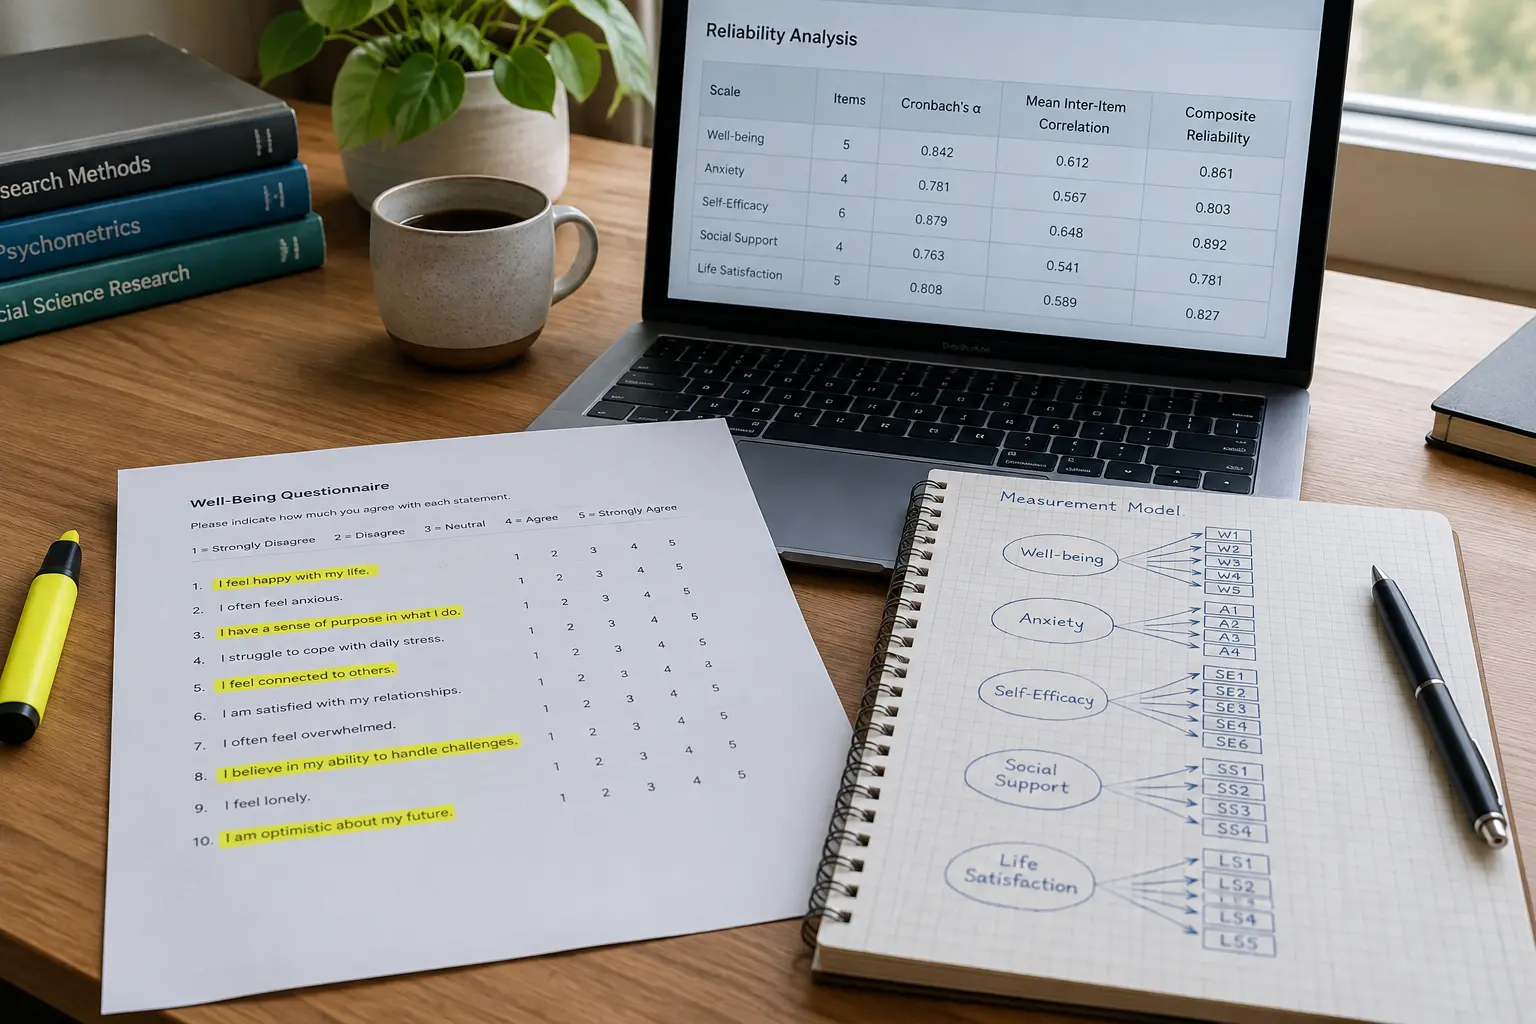
Examiners expect two separate things: evidence that your instrument measures the construct you say it does (validity), and evidence that it measures it consistently in your own sample (reliability). A single Cronbach’s alpha does not cover both. Report what you did, why it fits your design, and what the numbers do and do not show.
What is the difference between validity and reliability in a PhD thesis?
Reliability is about consistency: would the same instrument give similar scores for the same people under the same conditions, or would two coders agree about the same transcript? Validity is about meaning: are the scores a defensible measure of the thing your research question is about? An instrument can be perfectly consistent and still measure the wrong construct, which is why a high reliability coefficient never settles the validity question.
In a UK viva this distinction is usually tested in one sentence. An examiner reads that a scale “was validated (α = 0.87)” and asks which kind of validity that number is supposed to demonstrate. The honest answer is none: alpha is reliability evidence. The rest of this guide sets out what a doctoral methods chapter needs to say instead, and where the common mistakes sit. It applies to anything that produces scores: questionnaires, tests, rating scales, observation checklists and qualitative coding schemes that you quantify.
Which kinds of validity evidence do examiners look for?
There is no universal list that every discipline applies in the same way, so check how your own field and supervisor use the terms. Four categories cover most doctoral methods chapters.
- Content validity. Do the items cover the whole domain of the construct, and only that domain? This is usually shown through a structured review by experts, not by the candidate alone.
- Construct validity. Do the scores behave as the theory says they should? Typical evidence is a factor structure consistent with the claimed dimensions, correlations with related measures that are higher than correlations with unrelated ones, and differences between groups that theory predicts.
- Criterion validity. Do the scores relate to an external standard, either a gold-standard measure taken at the same time or an outcome observed later?
- Face validity. Do the items look sensible to the people answering them? This is a useful pilot check, but examiners treat it as weak and informal and do not accept it as a substitute for the other three.
You rarely need all four. What you need is a justified choice. A doctoral thesis that develops a new instrument is expected to gather several kinds of evidence. A thesis that uses an established scale is expected to show that the published evidence applies to its own population and to compute reliability on its own data. The balance between the two is the single most useful thing to tell the examiner in the methods chapter.
What reliability evidence should you report?
Match the type of reliability to the type of instrument.
- Internal consistency for multi-item scales. Cronbach’s alpha, introduced by Cronbach (1951) in Psychometrika, is the default. Report it for each subscale rather than for a whole multi-dimensional instrument, and report it for your sample.
- Test–retest reliability where the construct is expected to be stable over the interval you choose. State the interval and why it is long enough that people do not simply remember their answers and short enough that the construct has not genuinely changed.
- Inter-rater reliability where people code, rate or observe. Report how many raters, how many cases were double-coded, the agreement statistic you used (percentage agreement alone is rarely enough), and how disagreements were resolved.
Two papers are worth reading before you write this section because they deal with exactly how alpha is used and reported: Tavakol and Dennick (2011), “Making sense of Cronbach’s alpha” in the International Journal of Medical Education, and Taber (2018), “The Use of Cronbach’s Alpha When Developing and Reporting Research Instruments in Science Education” in Research in Science Education. Both are short enough to cite properly rather than repeating a rule of thumb you cannot source.
How do you show content validity with an expert panel?
If you wrote or substantially changed items, a panel of experts rates each item for relevance to the construct. Two indices are widely used in doctoral methods chapters. Lawshe (1975), in Personnel Psychology, proposed a content validity ratio for each item based on how many panellists judge it essential. Aiken (1985), in Educational and Psychological Measurement, described coefficients, including V, that range from 0 to 1 and are computed from the ratings relative to the maximum possible sum of differences, with tables of probabilities for small numbers of raters. Whichever you choose, state the number of experts, why each qualifies, the rating scale they used, and where your cut-off comes from. An unreferenced cut-off is a common reason for a query.
Here is a fully illustrative example with invented numbers, showing the arithmetic an examiner may check.
- Content validity ratio. The ratio is CVR = (ne − N/2) / (N/2), where N is the number of panellists and ne the number rating the item essential. With N = 8, an item that 7 rate essential has CVR = (7 − 4) / 4 = 0.75; an item that 6 rate essential has CVR = (6 − 4) / 4 = 0.50; an item that all 8 rate essential has CVR = 1.00.
- Aiken’s V. The index is V = S / [n(c − 1)], where S is the sum of each rating minus the lowest possible rating, n the number of raters and c the number of rating categories. Suppose 5 raters use a 4-point relevance scale and give an item 4, 4, 3, 4 and 3. Subtracting the lowest category (1) gives 3, 3, 2, 3, 2, so S = 13 and V = 13 / (5 × 3) = 0.87.
The numbers matter less than what you do with them. Say which items were revised or removed after the panel, and keep the revision log in an appendix so that the examiner can see the instrument changing in response to the evidence.
How do you show construct validity without overclaiming?
For a newly developed scale, construct validity usually means exploratory or confirmatory factor analysis, plus correlations with measures of related and unrelated constructs. The risk is overclaiming from a small dataset. Factor analysis is sensitive to sample size and to the number of items per factor, so a pilot of thirty participants cannot support a claim about structure, even if the output looks tidy. Say that the pilot was used for wording and timing and that the structure was tested on the main sample.
For an established scale, you are not expected to re-derive the structure in every study. You are expected to cite the original validation evidence, state the population it was developed in, and explain why your population is comparable. Where you suspect it is not comparable, a confirmatory check on your own data is the honest solution, with the limitation stated if the sample is too small to run it. The related question of how big your sample needs to be is covered in sample size rules for postgraduate nursing and health research, and the reasoning applies well beyond nursing.
What about translated and adapted scales?
A scale validated in English is not automatically valid in another language or culture. If you translated it, describe the procedure (independent forward translations, reconciliation, back-translation, review by a panel, and cognitive interviewing or a pilot are the usual elements), and report reliability and, where possible, structure in your sample. If you shortened a scale, dropped items or changed the response format, you have created a different instrument and should say so. The consensus-based standards for health measurement instruments, known as COSMIN, set out a taxonomy and checklist for judging the quality of studies on measurement properties; Mokkink and colleagues (2010) describe them in the Journal of Clinical Epidemiology and in Quality of Life Research, and the vocabulary is a useful structure even outside health research.
Where do candidates get caught out?
Examiners raise the same handful of problems again and again. Reading your own chapter against this list is faster than waiting for the viva to find them.
- Alpha offered as proof of validity. It is reliability evidence only.
- Reliability copied from the original paper. Report your own coefficient and treat the published one as context.
- One alpha for a multi-dimensional scale. Report it per subscale, or explain why a total score is justified.
- Very high alpha treated as automatically good. A very high value can reflect redundant items. Discuss it rather than celebrate it.
- Reverse-coded items not recoded. This silently lowers alpha and is easy to miss.
- “Validated” used loosely. If the evidence is content review and a pilot, say that, not “fully validated”.
- Unreferenced thresholds. Any cut-off for acceptable alpha, CVR or kappa needs a source, and conventions differ between fields.
- Percentage agreement as the only inter-rater statistic. It does not account for agreement expected by chance.
A worked, illustrative alpha calculation shows what the coefficient actually is. Alpha = [k / (k − 1)] × [1 − (Σσi² / σt²)], where k is the number of items, Σσi² the sum of the item variances and σt² the variance of the total score. With k = 10 items, item variances summing to 12.0 and a total-score variance of 40.0, alpha = (10 / 9) × (1 − 0.30) = 1.111 × 0.70 = 0.78. Reporting the inputs, not only the output, is how you show the examiner you know what the number means.
What should the methods chapter actually say?
Treat the instrument section as a short, structured argument. A workable order is below, and it fits equally well in the methods chapter of a thesis in psychology, education, management or health.
- Name the construct and its definition as used in your thesis, and say which theory defines it.
- Describe the instrument: author, year, number of items, subscales and response format, each taken from the source you cite, not from memory. If you are choosing between several established scales, PHQ-9 vs GAD-7 vs DASS-21 vs WEMWBS shows what a comparison of developers, licensing and fit looks like.
- Summarise the published validity evidence and say whether it was gathered in a population like yours.
- Report what you did yourself: expert panel, translation, pilot, cognitive interviews, with numbers and dates.
- Report reliability in your sample, per subscale, with the coefficient and its inputs where practical.
- State the limitations that follow, for example a small pilot or a convenience sample, and carry them into the discussion chapter.
The step-by-step mechanics of writing items, building an instrument matrix and running a pilot are in how to design data collection instruments for postgraduate research, and the way a construct becomes a measured variable is shown in building a variable operationalisation matrix. If your thesis is qualitative, the equivalent vocabulary is trustworthiness rather than validity and reliability, and the examiner objections to a nursing PhD show what demonstrated, rather than claimed, rigour looks like. For the wider picture of what examiners say about methods, see what PhD examiners actually write in their reports.
What do I do if the numbers are disappointing?
Report them. Low reliability is a limitation to be discussed, not a result to be hidden, and an examiner who finds that you removed items silently will trust the rest of the chapter less. Check for subscales, coding errors and reverse-keyed items first, then say what the weaker measurement means for your conclusions: attenuated correlations, wider confidence intervals, or a finding that should be read cautiously. Being specific about the consequence is far better received than a general apology.
Frequently asked questions
Is Cronbach’s alpha enough to show that my questionnaire is valid?
No. Alpha is a statistic about internal consistency, which is one kind of reliability evidence. It says nothing on its own about whether the items measure the construct you claim. Validity needs separate evidence such as expert review of content, a defensible factor structure or relationships with related measures.
Can I quote the reliability figure from the original scale paper?
You can report it as background, but examiners expect you to compute and report reliability in your own sample, because reliability is a property of scores from a particular group on a particular occasion.
Do I need an expert panel if I use a published scale?
Not for the original scale in its original population and language. You do need to show that it suits your population, and a translated or substantially adapted scale needs its own evidence of adaptation.
What is the difference between content validity and face validity?
Face validity is whether items look sensible to respondents, which is a weak, informal judgement. Content validity is a structured judgement, usually by a panel of experts, of whether the items represent the construct domain.
How many experts do I need for a content validity panel?
There is no single required number. Lawshe’s content validity ratio is calculated from the number of panellists, so state how many you used, why they qualify as experts, and which index and cut-off you applied and where it comes from.
Does a pilot study count as validation?
A pilot is evidence about feasibility and wording. It can supply early reliability estimates, but a small pilot rarely supports claims about factor structure, so describe what the pilot was used for and no more.
What do I report for a coding scheme or observation checklist?
Report inter-rater agreement, for example Cohen’s kappa for categorical codes or an intraclass correlation for ratings, along with how many coders, how many cases they double-coded and how disagreements were resolved.
What if my alpha is low?
Report it honestly, check whether the scale has several subscales that should be analysed separately, check for reverse-coded items entered incorrectly, and discuss the consequence for your findings as a limitation rather than quietly dropping items without explanation.
Do qualitative theses need validity and reliability?
They need rigour, but usually under different vocabulary such as trustworthiness, credibility and dependability. Use the framework that fits your design and show the technique behind each claim.
Where does all of this go in the thesis?
Instrument description and the validity evidence you gathered belong in the methods chapter. Reliability coefficients from your own data can be reported there or at the start of the results chapter, as long as you say which, and limitations belong in the discussion.
Getting the methods chapter to say all of this
The structure above is easy to list and harder to write cleanly across a chapter you have been drafting for months. Tesify is used by 9,000+ students across 15,000+ chapters to organise a thesis chapter by chapter, and the thesis stays 100% written by you. The measurement evidence, the numbers and the judgement calls remain yours; the structure simply helps you check that none of them has gone missing.